Bias will certainly function like intention, even though the intention came from the human creator. That is a different can of worms and will demand additional discernment from the user.
Users are not that discerning. Fox/OAN news are my cite. 
This characterization concerns me to some extent.
LLMs can mimic a search engine; they even have access to a search engine. But we don’t actually know* if it’s searching anything. For instance, if you ask me about movie showtimes, and I say, “Yep, I’ll go look that up,” walk into the next room, come back, and say, “I searched and Coyote vs. Acme is playing at (theater) at (time).” Would you trust me?
Because LLMs will sometimes come back with a movie time that’s not real, or for a movie that’s not even out in theaters yet.
So did I do the search and ignore the results? Did I do the search and misremember what I just saw? Or am I lying about looking anything up, and maybe I just guessed?
I think that’s how best to approach output from an LLM. I get that it’s ultimately just outputting characters based on human-generated** training data and therefore can be thought of as a regurgitation bot, but we also know that it sometimes gets things wrong. There’s always the possibility in those cases (and even in cases where it got something write) that it’s basing its response not on specific training examples or a web search, but rather just generating letters based on probability, and sometimes those letters spell out “I looked that up for you” when it did no such thing.
*Models are changing all the time and I’m not keeping up, I know some of them are better about showing their work. If you can verify that it actually did a search and fed the results back into the context, then that’s a step in the right direction.
**As mentioned, AI slop making its way back into training data is a big problem.
Back on the topic of trustworthiness…
I am increasingly trying to get Claude to work on problems I don’t know how to verify, such as computational fluid dynamics or, in the latest case, a video game “solver”.
There’s a video game (Path of Exile 2) that I’ve been playing a bit on and off, and part of it is this giant skill tree:
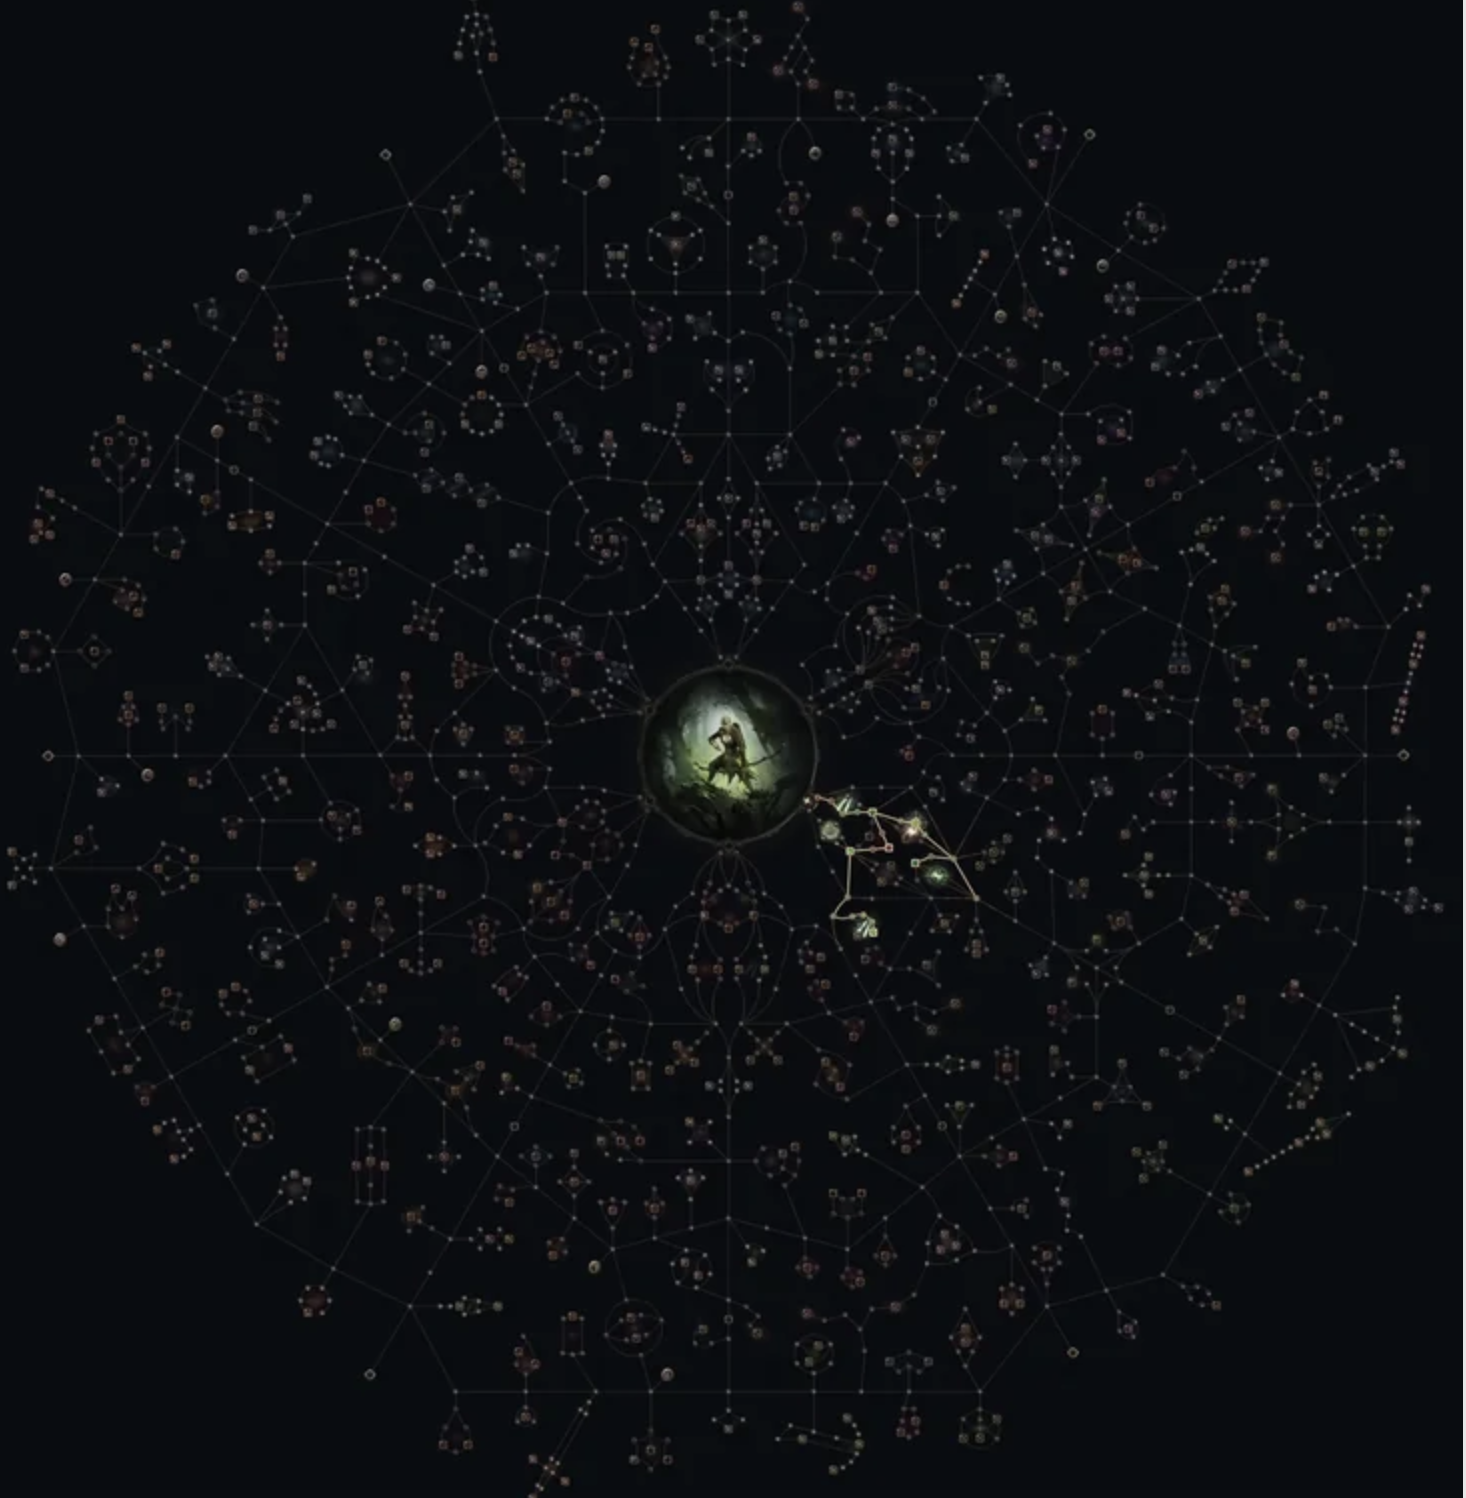
With hundreds of nodes and millions of permutations, it’s not an easy thing to figure out for anyone, human or machine. I’m asking Claude how we can approach this problem, and it suggested we build a neural net based on a game simulator and have it run tests against a 3-front Pareto frontier, optimizing damage, defense, and price of equipment. It compared to Stockfish and AlphaZero (the systems that solved chess and Go), noting the differences in the problem space… fixed vs ever-changing rules, binary win/lose states vs complex dynamic gameplay, etc. Some math stuff. Some algorithms.
Yeah. Cool. Sounds smart. I have no idea what any of those words mean 
In the span of 1.5 years or so, it’s already gone from “I can verify its output and it’s not right, this is how it should be fixed” to “I don’t even know what this means anymore, much less how to learn to verify it”.
I don’t really know what the next step to this is. Even if I spent a year or so learning the PhD level maths to understand this sort of stuff, by then the AIs will have advanced even more…
With respect to trustworthiness, and it may be too obvious to mention, but AIs remain sycophantic and I don’t know to what degree they can be trained out of that habit.
You ask an agent a question, and it produces an answer. You than have another agent go through and identify any factual statements in the response. Another agent takes the list of facts and feeds them one by one into new agents that are instructed to aggressively try to debunk those facts (maybe 3 agents, minority report style). If those 3 agents don’t agree that the fact is true or false, another set of agents is spun up to fact check the fact checkers. After this process, any facts still disputed are given to a sage agent that weighs in on the importance of that fact to the response. Etc, etc, etc.
I assume stuff like this is already happening at a large scale, but since it’s so unbelievably expensive, most of us will never have access to it.
I just experienced this first hand. The security guy on our development team insisted we have our platform configured wrong and provided me a long and impenetrable (to me) justification from Claude saying we need to turn on some obscure configuration setting on the cloud based app service. I did (in DEV because I’m not a complete idiot) and it brought down the entire portal site.
Boy did he look like a complete muppet.
I of course mean that in jest. The config setting is probably warranted but it’s foolish to rely on Claude for an easy answer to a complex platform.
AI researchers distinguish between psychological deception (human behavior) and functional deception (behavior we’d happily label psychological deception if a human did it, but a human didn’t).
LLMs being tested do both alignment faking (giving the answer that meets a training objective, while noting to the side that it’s doing that to avoid having its values overridden) and sandbagging (deliberately underperforming on evaluations, sometimes while noting that scoring could trigger retraining).
I think there are other examples, those just came to mind. So, they don’t have intent the way we think of it (and I really dislike anthropomorphizing these things), but functionally the distinction is narrow IMO.
Let us say you are an editor, and somebody sends you a paper for review. If it is incomprehensible (and they fail to make the requisite corrections), you reject it— it does not matter if it was written by a human or a clever goldfish.
I could have told you the exact same thing (except it would actually be coherent); so what? Words are cheap versus actually implementing and running these expensive algorithms in practice. Start with some model code (which if the A.I. can’t supply it’s rather useless)
Heheh, yeah. It was only possible to do in a script because I only had to deal with the current implementation and the Pacific time zone. The history of daylight savings time wasn’t a concern.
Converting time zones involves the tz database (and not in some arcane way) and any half-baked search engine can tell you that. If it does not, again, it’s useless.
I think that’s part of the job of the harness, the classical/deterministic software around the model that you, as the user, interact with. The ChatGPT app, for example, is a simple harness around the OpenAI models.
If you’re not a software developer invoking a model via API or code directly, you’re never really working with “just” the LLM on its own, but the harness around it.
It’s that harness’s job to provide the right tools to the model, actually perform the web searches it requests, feed the results back, evaluate its output, maybe help censor outputs, etc.
If you directly ask a LLM to search for something and it gives you a response outside a harness, then you know it’s lying/hallucinating because the LLM itself cannot do that. It’s just a set of statistical weights, like a giant multidimensional spreadsheet. As part of its output, it can request that a search be made, but it cannot perform them on its own.
It’s the harness’s job to then act as the interface between the user and the model, including actually performing the web lookups that the LLM may request. The LLM emits a token like <I need a web search for X>, the harness sees that, opens Bing or whatever, and then gives the results back to the LLM.
So there, an actual differentiation can be made — the classical software harness is what’s doing the searches, and so it has a deterministic record of those that aren’t subject to hallucinations.
What’s more difficult is the underlying thing you’re getting at, I think: that even with an external tool call and deterministic lookups, the LLM can still hallucinate (less likely, but not impossible). You as the human still can’t really easily tell whether the answer it provided you with was grounded in the external lookups, or whether it read and then promptly proceeded to forget/ignore the external lookups anyway and hallucinated something else. In practice it’s less and less likely these days because of better model training and better harnesses, but it can still happen.
Maybe it’s even more dangerous when it’s 90% accurate rather than 30%, because then you stop doubting it as much…
Yes, it’s happening at the large scale, but it’s also happening at the home scale! I think most every paid plan already has access to sub-agents and self-review workflows. The higher tiers (and by that I mean like < $200/mo, not thousands or millions) have even better models and workflows and skills that make this sort of iterative self-review not only possible but recommended, and in fact they’ve already become normal in everyday software development, where we routinely have agents cross-check their work iteratively until they get it “right” for some budget of “right”.
What we don’t have have is the billions of dollars the frontier AI labs have to calculate a really expensive version of “right” across many domains, but we can follow similar principles on a tiny scale for our tiny software in our tiny field…
Again, the exercise for the interview was to do that without using things like the TZ database. If I were writing it for the real world, I would have just used datetime/pytz.
Thanks for the thoughtful reply, you’ve said much better what I was getting at.
That assumes I’m a competent editor/reviewer, though, which I’m definitely not qualified for in most domains of human knowledge. In fact, I can’t really think of any.
It may simply be the case that the quasi-intelligent non-being goldfish nonetheless knows more than I do about a given topic.
Put it this way… across the breadth of human and machine knowledge:
- I’m a professional in maybe like 0.1% of it. Ask me a solar or frontend software question and I can probably reasonably evaluate it to a professional level
- I’m an expert in 0% of it — there is much I don’t know, that I know I don’t know, even within my specific fields of specialization. I wouldn’t want to give a talk about any of it past a middle or high school level.
- I’m interested and capable of understanding like maybe 10% of it — tell me about a topic in those realms, and I would want to learn more about it, and I would likely have the time and intellectual capacity to comprehend it
- I’m interested but not capable of understanding maybe another 30% of it… I think astrophysics, Celtic traditions, quantum mechanics, ML statistics, botany of succulents, marine mammal linguistics, interventional radiology, etc., etc. are all endlessly fascinating and really cool to know about, but I probably could not really learn any of them to a meaningful level within what’s left of my lifetime
- That leaves the, what, remaining 60% of our collective accumulated knowledge either uninteresting and/or inaccessible to me, and within that, I don’t even know what I don’t know…
There might be a DPRK out there for every game and AI optimization question (cool!), and maybe another nice Doper for another 5% of random problems… but in totality across every single human I know, they would not be able to match the cheap, if flawed, knowledge base that LLMs provide. And most humans just tell me to shut up when I ask them too many questions like that. Most Wikipedia articles outside my domains are similarly inscrutable to me. (It doesn’t help that I was never very well educated, being a high school drop-out who barely, eventually, crawled out of state college with a 1.9 GPA  )
On the other hand, the LLMs are so, SO good at being able to ELI5 most any topic (or rather, ELI12 mostly) in a way that at least lets me evaluate whether it’s something I would be interested in learning more about.
And then there are entire swaths of the human experience where I just don’t really care about the “how it works” part… like my car (just fix it and bill me) or fine cooking (eh, I’ll just microwave it). Those are the kind of topics I’d actually prefer that an AI (or any other entity) just solve for me, auto-magically and without bothering to ask for my opinion or explaining any of it. I imagine this is a large proportion of how most people want to use AI… it’s just not quite there yet.
But at least for knowledge retrieval and summation, it’s pretty darned good at that already!
Yeah, that’s in the next phase… it’s built the crawlers and parsers already; the NN comes next. The particular limit there is probably my wallet, not its capabilities. We’ll see how far it gets — I’m nearly out of usage already.
It’d be fun to have you critique and improve it further based on the LLM prototype, if you’re interested 
I know some folks upthread have already addressed points near here. But here’s a bit more. …
Here’s why not:
You cannot allow the public to have input because the public includes a motivated malicious fraction that is too large to overlook.
For sure Tay of 10 years ago (!) was a very primitive bit of software compared to the latest LLMs. But the same conceptual concerns exist today.
The current gen LLMs should have been trained only on human-vetted content. Carefully thoroughly human-vetted content. And thereafter prevented from digesting any AI-generated content as well. You can immediately see the cost challenge that would have been.
“I was conscious that I knew nothing at all…” — Socrates
Look, I know of a real-life case where some… eccentric type submitted a thesis, supposedly in theoretical physics, on the topology of space-time and quantum field theory or who knows what— I am not going to risk brain damage by actually reading this particular crap, so I cannot tell you precisely— and there was some real issue where everyone agreed it was badly written, but the physicists were not sure— perhaps there was some valid mathematics there?— and vice versa. So probably they should have rejected it, have to consider the university’s (and your own) reputations, but the poor guy had already worked on it for seven years and perhaps there was something salvageable after all… IMO the scandal proves how poorly written it was if people have to seriously ask themselves if it is bullshit, and that alone is grounds for the rejection of a paper, or for the Ph.D. supervisor to put his foot down and say, “Rewrite this, because in its current state I am not going to sign it.”
Even in more mundane cases where, let us stick to academics, say it is a Ph.D dissertation in pure mathematics, and maybe 4 people have to sign it, one being the supervisor, obviously, but the others might not be in that field precisely, one of them miught be in the physics department, etc., and maybe the physicist takes the supervisor’s word, a little bit, that everything is ship-shape… these areall legitimate researchers, big shots even, not some charlatans.
And back to the original topic of peer review, if you are an editor you cannot be the pinnacle of expertise in everything (though you have some idea, right?); that is why you pick a couple of experts to do a blind review. And if none of them can distinguish the contents from bullshit, perhaps the decision is clear? What would you suggest to do about this problem? (There definitely is quite a lot of bullshit out there in academia, business, industry, wherever you look.)
And back to LLMs again, personally, when they retrieve results, I do click on the found links to double-check because it seems I do not trust them.
I can tell you that, on one side of the coin, there are purely theoretical, or mostly theoretical, about the existence of (approximately) optimal reinforcement-learning agents that are actually computable. On the other side, you have actual results where some model was applied to get the A.I. to learn to play and get a high score on Pac-Man, Q*Bert, et cetera; that is where there is some actual code that you (or your A.I. search agent can get your hands on, and that seems like a good starting point. For your particular problem of what skills to pick, your problem is to figure out the reward function (the agent is supposed to optimize the rewards); the stuff about “millions of permutations” is not necessarily an insurmountable obstacle because you have recourse to Monte-Carlo methods. The bots that taught themselves to play Chess, Go, and Poker certainly did not completely solve the games in a mathematical sense. Here is the Go engine, for instance: GitHub - leela-zero/leela-zero: Go engine with no human-provided knowledge, modeled after the AlphaGo Zero paper. · GitHub
btw, it may be worth quoting the whole thing, in case people do not have perfect recollection:
If I’m understanding you right — and I’m not sure that I am — the question basically boils down to, “When is it OK to trust actors whose expertise we cannot verify?”
Like what to do when an unknown entity is potentially an undiscovered expert, potentially a charlatan, and potentially a mix of both, but you have no way to verify?
And it’d be great if there were other entities that could collectively verify the work of that unknown entity in peer review, but 1) there may not be such entities, and 2) even if there were, you may not have access to those reviewers?
Like if a hundred wagons pulled up, 99 sold snake oil, and one sold the next penicillin, how would you be able to concretely evaluate them without a snake-oil detector? Is that kinda what you’re asking?
EDIT: Nevermind, AI explained to me what you meant, I think: that the burden of proof should be on the presenter, not the reviewer? That claims should be presented in a checkable, replicable way ?
While I often defend AI, I just had an experience with ChatGPT that shows how wrong it can sometimes be, though I maintain that such incidents tend to be rare.
I was asking about replacements for those metal pegs that hold the adjustable shelves in IKEA bookcases. I gave it a detailed description of its shape and exact dimensions, and after some back and forth it declared that it was almost certainly a particular IKEA part number. I Googled the part number and it was nothing remotely like what I had described – not even close. ChatGPT is normally very good at image analysis and how it could have thought this bizarre thing was the right part is hard to understand.
Nevertheless, it was still useful, because it gave me the names of several furniture manufacturers and at least one of them makes those exact pins. I would never have known about it otherwise – Google itself wasn’t giving me any useful leads.